Research Release: Ypru-100M Baseline Validated on H100

Sovereign Base Models.
Fixed Constant O(1) Memory.

Yaqgu is an independent research lab engineering foundational sequence architectures. By decoupling memory scaling from sequence length, our Ypru foundation model family delivers infinite context and high-throughput edge execution with zero KV-cache memory explosions.

✓ 100M Tokens Pre-Trained ✓ Flat 424MB Context VRAM ✓ 100% Permissive Open Data ✓ 7.3μs Constant Decode
Inspect Ypru-100M Weights on Hugging Face → GitHub Runtime & Specifications

Institutional Structure

The Yaqgu Ecosystem

Engineered as a clean separation between foundational machine learning research and edge deployment systems.

Y
The Systems Platform

Yaqgu Technologies

Autonomous Intelligence & Edge Runtimes

Yaqgu is the parent systems engineering company. We develop privacy-first in-browser agent frameworks, local WebGPU execution layers, and enterprise serverless inference orchestration designed to eliminate cloud GPU hosting premiums.

Focus Area: Edge Runtimes & Autonomous Browser Agents
Serving Paradigm: Zero-Cloud-Cost Local Inference + Serverless
Commercial Operations: Enterprise SLAs & Custom Deployments
Ψ
Foundation Model Series

Ypru Base Architecture

Sample-Efficient Linear Sequence Recurrence

The core intelligence series powering Yaqgu systems. Ypru is an entirely sovereign base model family combining Taylor-expansion linear attention with dynamic neural memory gating to achieve linear sequence scaling with strictly constant VRAM.

Current Milestone: Ypru-100M (Loss: 4.2312)
Memory Complexity: O(1) Strictly Constant (424MB Flat)
Next Scale Milestone: 1.0B Parameters / 20B Tokens (Targeted for TRC)

Empirical Validation

Zero-OOM Hardware Scaling

Audited on NVIDIA H100 SXM5 compute infrastructure under real inference execution.
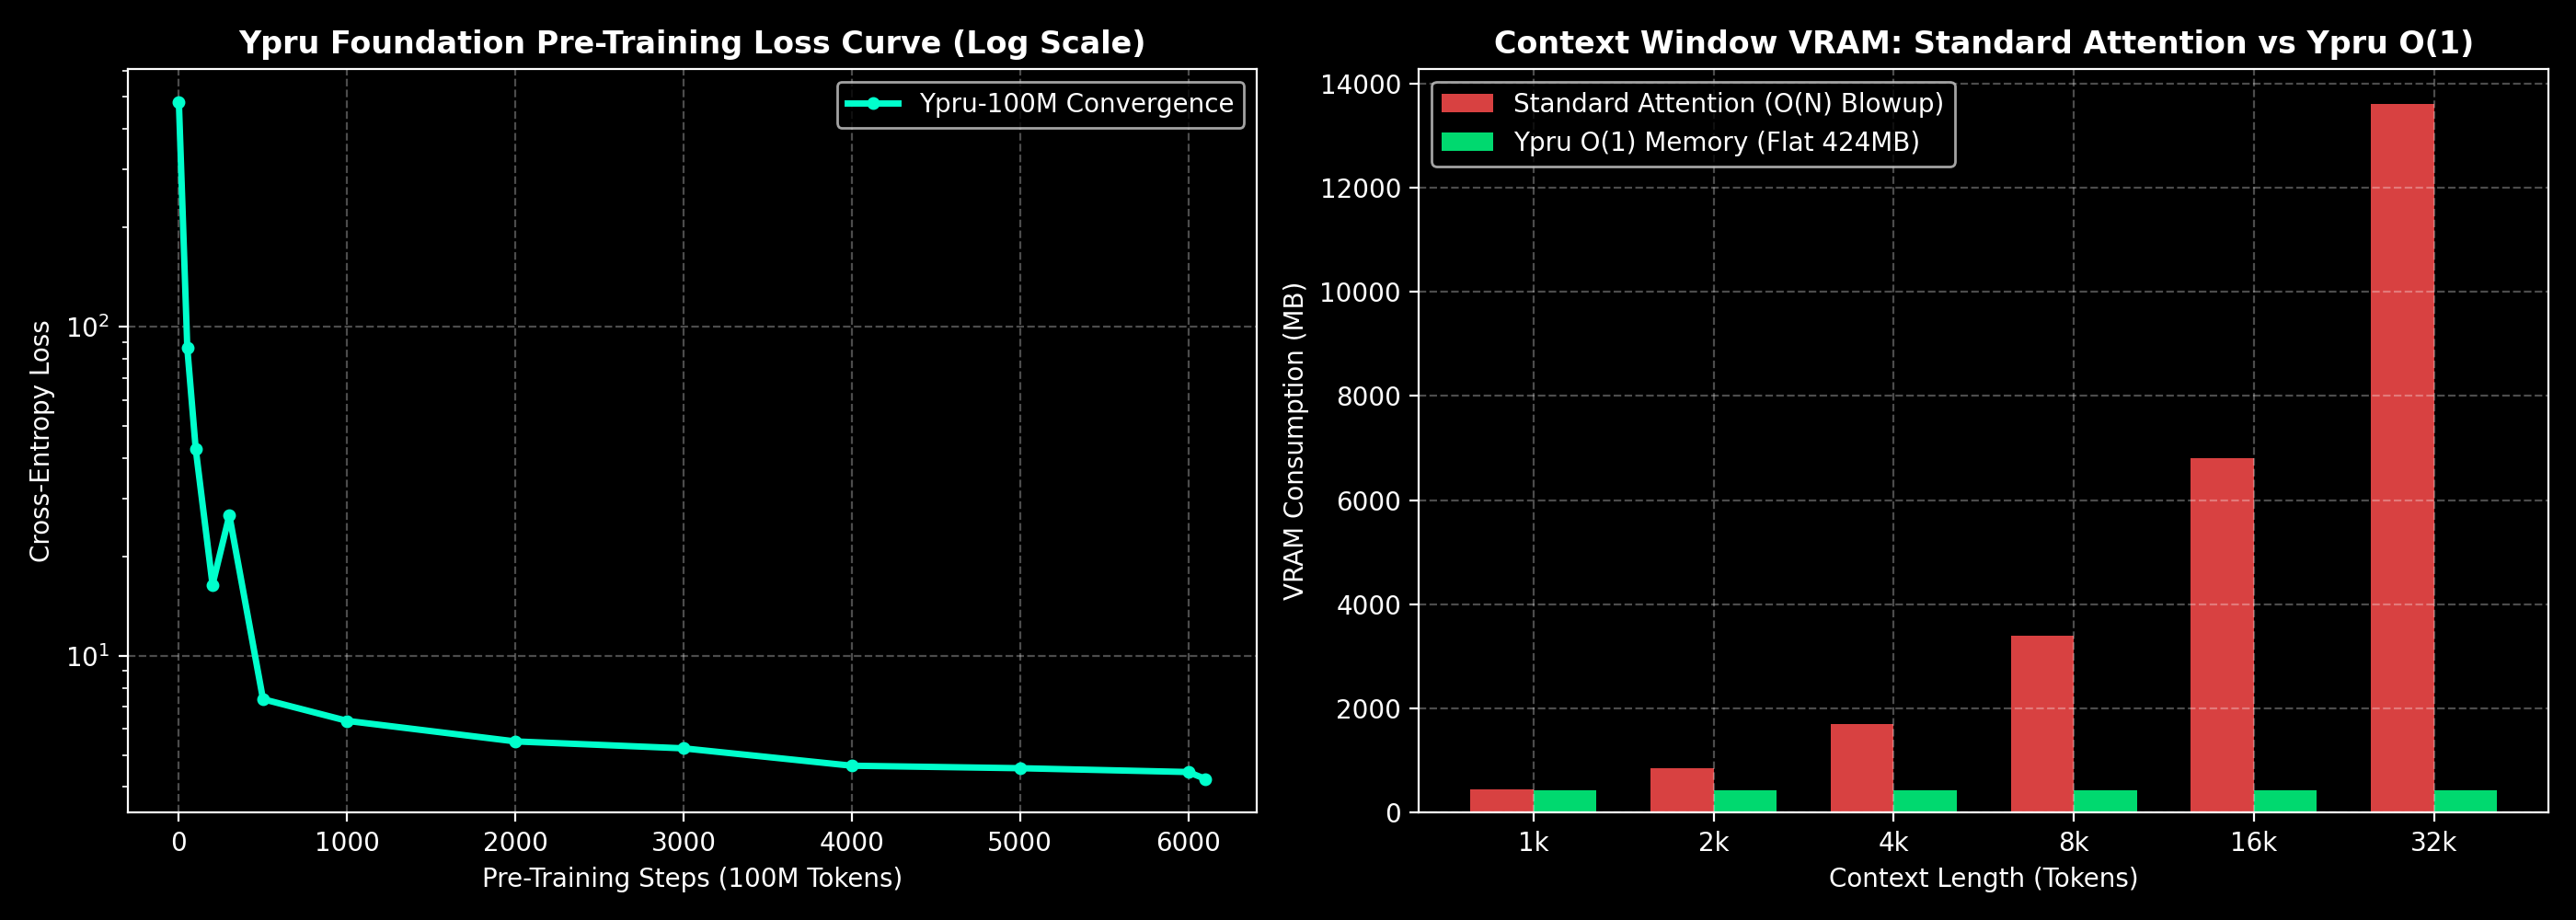
Ypru Pre-training Loss and O(1) Memory Scaling Benchmark

Pre-Training Volume

100,000,000

Permissive Open Tokens

Convergence Delta

479.76 → 4.23

-99.1% Error Reduction

VRAM at 32k Context

424.64 MB

0 MB Growth vs 1k Context

Optimization Engine

Muon + AdamW

Newton-Schulz Spectral Loop

Academic & Research Alignment

Open Science & Next Milestones

Yaqgu commits to open research, verifiable model weights, and transparent benchmark publishing.

100% Permissive Pre-Training

Pre-trained exclusively on gold-standard educational corpora: FineWeb-Edu (50%), Open-Web-Math (25%), and CodeParrot-Clean (25%). Free of proprietary distillation contamination or ToS conflicts.

Google TRC Scale Proposal

Currently scaling the Ypru architecture to a 1.0B parameter model trained across 20 Billion tokens using Cloud TPU Pods to establish an open benchmark for constant-memory linear attention models.

Dual Community Licensing

Model weights are released for free academic and personal evaluation under the Ypru Community License, with custom commercial licenses available for enterprise production integration.

Direct Execution

Load Ypru-100M via Hugging Face

# Load model directly using standard Transformers library

from transformers import AutoModelForCausalLM

model = AutoModelForCausalLM.from_pretrained("yaqgu/ypru-100m", trust_remote_code=True)

model.eval()

# Executes with O(1) fixed recurrent memory

output = model(input_tensor)